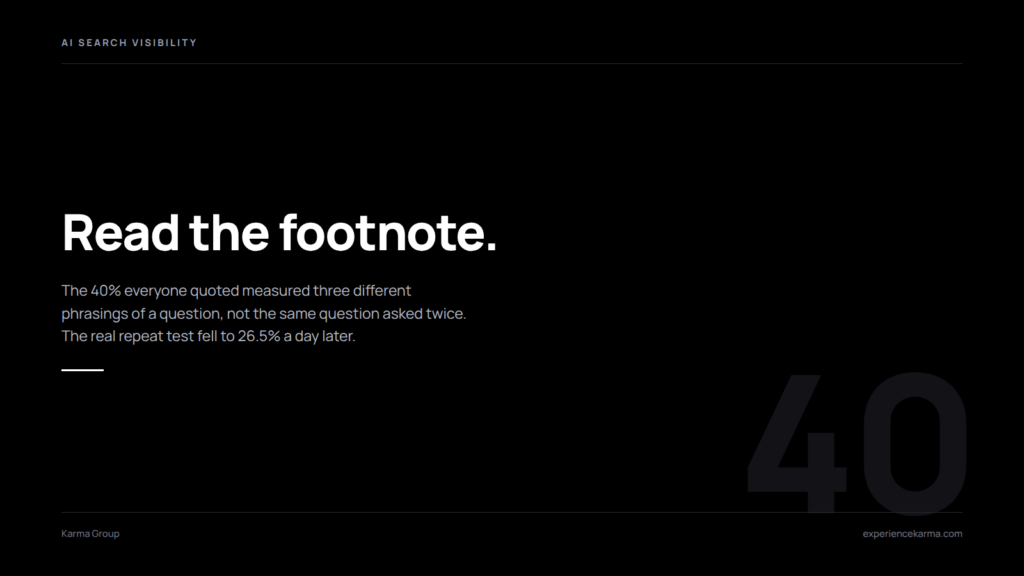
Search Engine Land reported on August 19 that repeating the same Gemini query returned overlapping sources only about 40% of the time. That number spread fast. But it does not mean what the coverage said. The 40% came from three different phrasings of one question, each asked a single time. Nothing in that dataset asked the same words twice. The true ask-twice test was far smaller, and it landed worse. There, AI citations overlapped 46.3% back to back, then slid to 26.5% a day later.
So the popular number is soft. Still, the finding underneath it holds, and it should change how you measure.
The 40% everyone quoted was never a repeat rate
The study is the AI Citation Ledger from Steady Demand, published August 6 and updated August 20. It logged 14,472 citations across 1,487 local queries, 50 US metros and 10 service categories, using Gemini’s grounding API.
Its main dataset varied the wording. One query asked for the “best” provider in a city. Another asked for the “top rated” one nearby. A third asked who is “a good” provider there. Each ran once. So the roughly 40% overlap measures something real but narrower than billed: how much the cited sources shift when a customer rephrases.
That distinction matters to you. Rephrasing sensitivity is a content problem, because it says your coverage is thin across question shapes. Instability on identical wording would be an infrastructure problem instead. A methodology review by Digital Applied flagged exactly this conflation.
The real repeat test was small, and it decayed fast
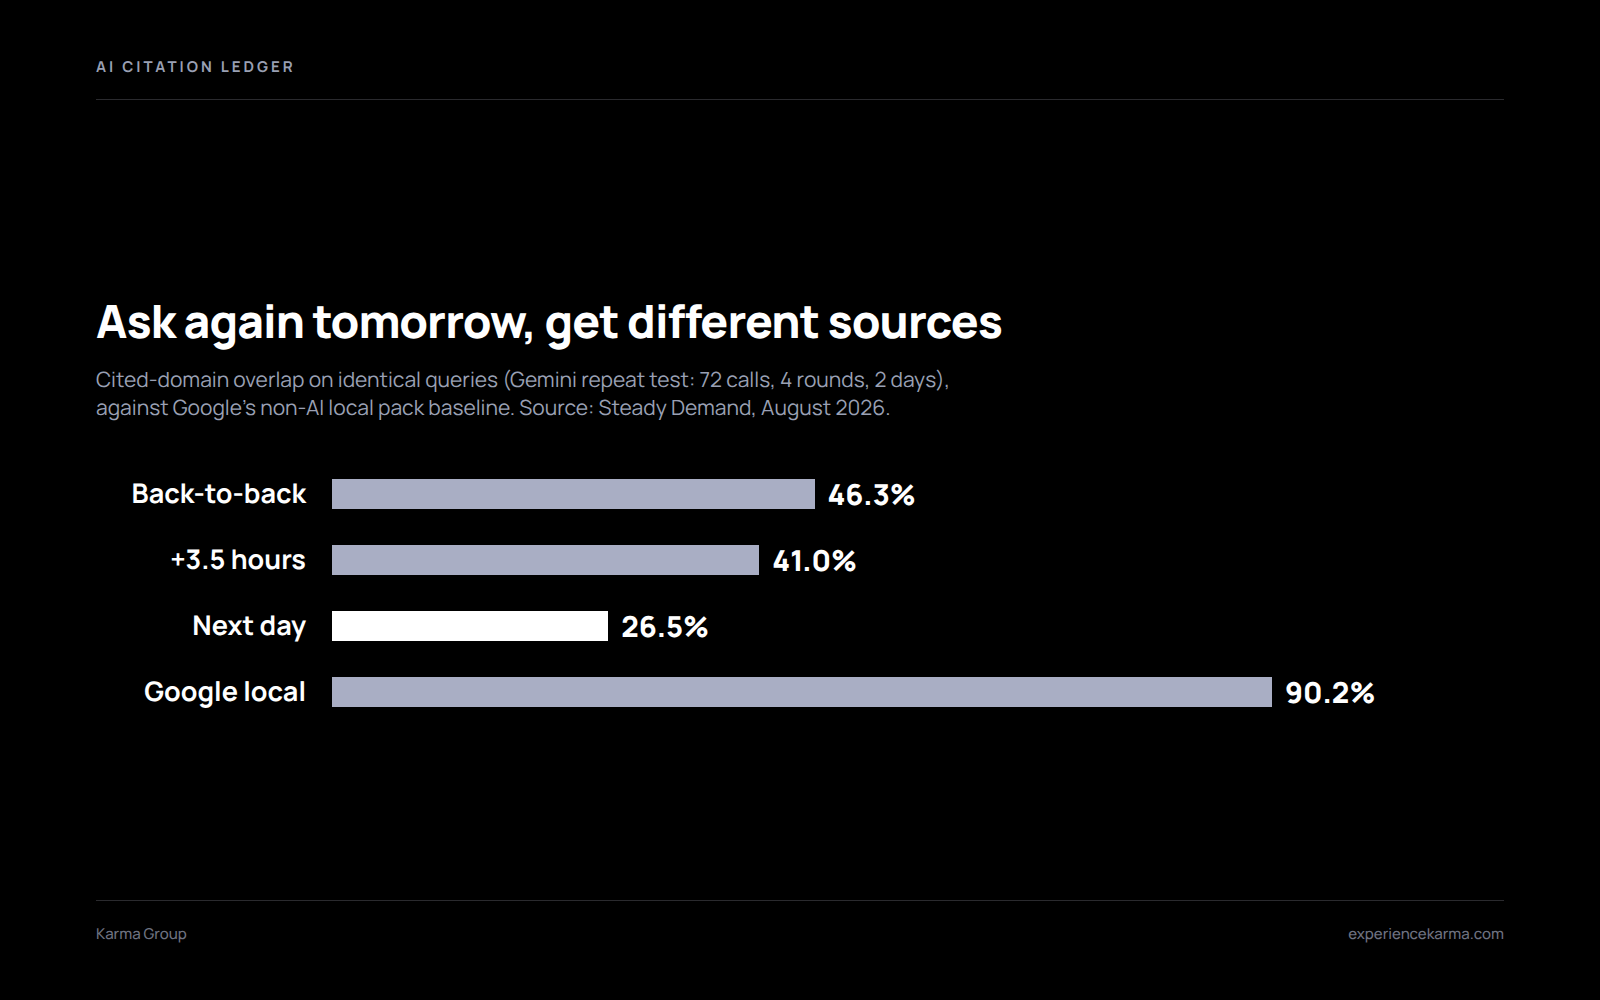
Steady Demand ran a second, separate experiment on identical wording. It logged 72 calls across four rounds, six fixed queries and two days, in one metro, on one engine. The numbers moved with the clock. Back-to-back repeats overlapped 46.3%. After roughly three and a half hours, overlap fell to 41.0%. The next day, about 19 hours later, it reached 26.5%.
Be honest about that sample. Seventy-two calls is a mechanism probe, not a population estimate. Steady Demand says so plainly, calling it a test “designed to isolate a mechanism, not to re-estimate the drift rate at scale.”
Yet the direction is the useful part. Overlap decays as time passes, so the gap between two checks predicts how little they will agree.
Google’s local pack holds steady at 90.2%
The control test is what gives the finding teeth. Steady Demand ran plain Google local searches as a baseline, across 4,466 pairwise comparisons and 500 metro-vertical combinations. The top listing stayed the same 90.2% of the time.
Compare that to Gemini’s next-day 26.5%. Classic local search behaves like a ranking, so one check tells you roughly where you stand. Generative answers behave like a sample instead.
Because of that, habits carried over from rank tracking will mislead you. You are not reading a position. You are drawing one card from a shuffled deck.
Two engines barely agree on AI citations
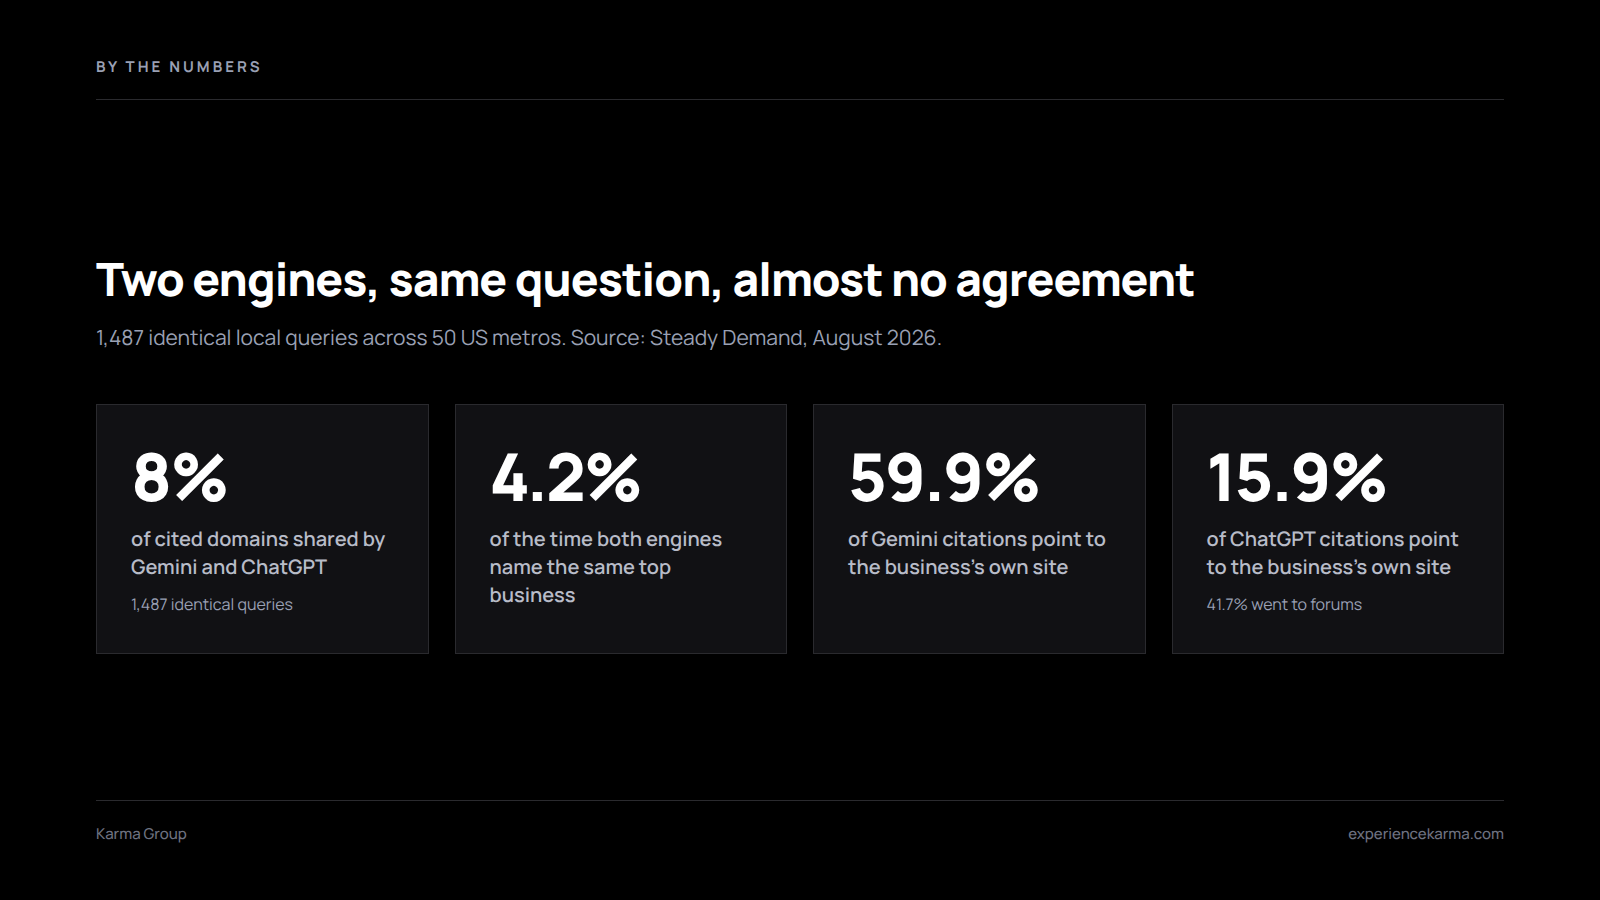
Across 1,487 identical queries, Gemini and ChatGPT matched on just 8% of cited domains. They named the same top business only 4.2% of the time. That is close to no agreement at all.
Their sourcing habits explain much of it. Gemini sent 59.9% of its citations to the business’s own website. ChatGPT sent only 15.9% there, while 41.7% went to social and community forums, and 34.6% went to general directories.
So a single “are we showing up?” test is doubly weak. It samples one moment, and it samples one engine. Reddit alone took 13.7% of citations in the wider dataset, beating every local-service directory combined at 10.3%.
One check tells you nothing about your AI citations
Here is the practical damage. A client asks whether they appear in AI answers. You run the query once, see the brand, and report a win. Next week you run it again, see nothing, and report a loss. Neither reading was information. Both were noise dressed as a metric.
The same trap catches vendors. Any tool that shows a single daily pull is reporting one draw from a wide distribution. Ask what sample size sits behind the number before you trust it.
In fact this is why AI citations resist the dashboard treatment. A percentage implies stability that the underlying system does not have.
Measure AI citations as a rate, not a status
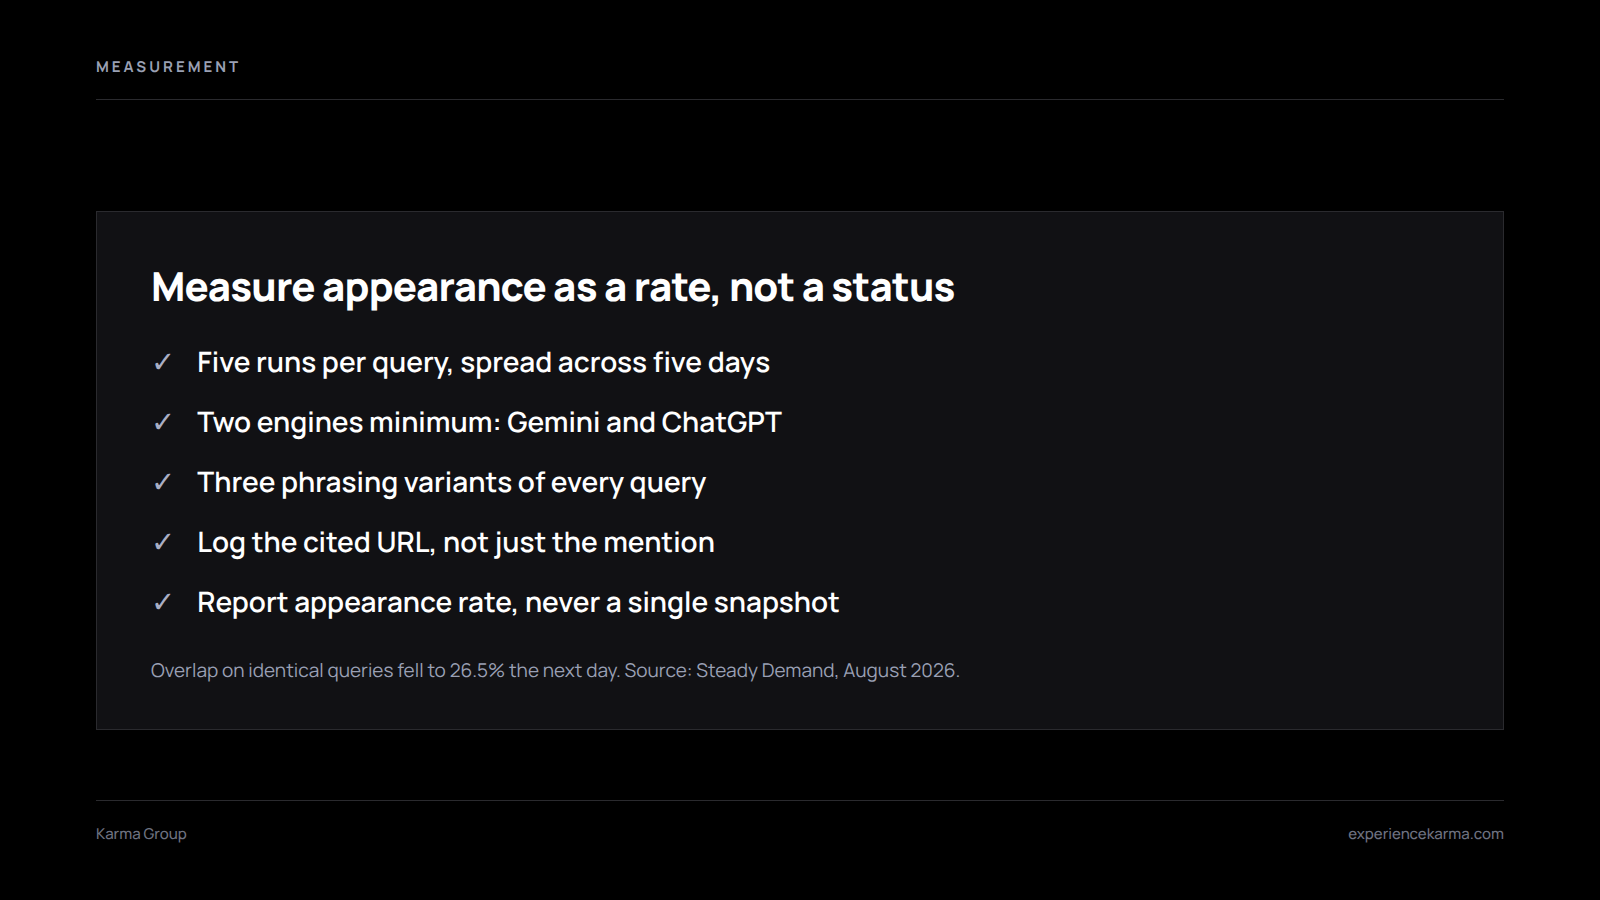
Swap the question. Stop asking “do we appear?” and start asking “in what share of runs do we appear?” That reframing fixes most of the problem, because frequency is stable even when any single answer is not.
Set a floor of five runs per query, spread across days rather than minutes. Overlap decayed most between days, so same-hour repeats will flatter you. Then run every query on at least two engines, since 8% domain agreement means one engine cannot stand in for the other.
Also vary the phrasing on purpose. Three shapes work well: “best”, “top rated near me”, and “who is a good”. If your appearance rate collapses on one shape, you found a content gap worth filling.
Fix the engine that is failing you, not both
Once you can see where your AI citations come from, the repair work splits cleanly. The two systems fail for different reasons, so one fix will rarely move both.
Say Gemini is where you are thin. Gemini sent 59.9% of citations to the business’s own site, so it is already willing to quote you directly. A low rate there usually means your pages do not answer the question in plain language, or they bury the answer below the fold. Write the answer first, name the service and the city in the same sentence, and keep the specifics on the page rather than in an image.
Now say ChatGPT is the weak one. Only 15.9% of its citations went to business sites, while 41.7% went to forums and 34.6% to directories. Rewriting your homepage will not help much. Instead you need to exist in the places it actually reads, which means accurate directory records, real review volume and genuine presence in community threads.
That split also settles a common argument. Teams often debate whether to invest in owned content or third-party presence. Given these numbers, the honest answer is that the choice depends entirely on which engine you are losing, and you cannot know that from one check.
Build the loop over the next two weeks
- Pick ten queries a real customer would type, not ten keywords you want.
- Write three phrasing variants of each, giving you thirty prompts.
- Run all thirty on Gemini and ChatGPT, five times each, across five separate days.
- Log brand mention, cited domain and position for every run in one sheet.
- Tag each row by engine, so AI citations stay separable when you report.
- Report appearance rate per engine and per phrasing, never a single snapshot.
- Re-run monthly, and compare rates rather than individual answers.
That is 300 observations per engine. It is enough to see a real move, and cheap enough to repeat. Meanwhile treat any month-over-month swing under ten points as noise until a second cycle confirms it. Most teams already own a tool that could run this, so the missing piece is usually the sampling design rather than the software.
One more habit worth keeping: log the cited URL, not just the mention. Gemini favours your own site, so a missing citation there points at your pages. ChatGPT leans on forums, so a gap there points somewhere else entirely. We covered the related split between citations and brand mentions earlier this month.
Want help making your AI citations measurable?
Karma Group builds this measurement loop for clients, then works the gaps it exposes. If your current AI visibility report rests on one query and one engine, we can show you what it is hiding. Get in touch and we will walk through your numbers.