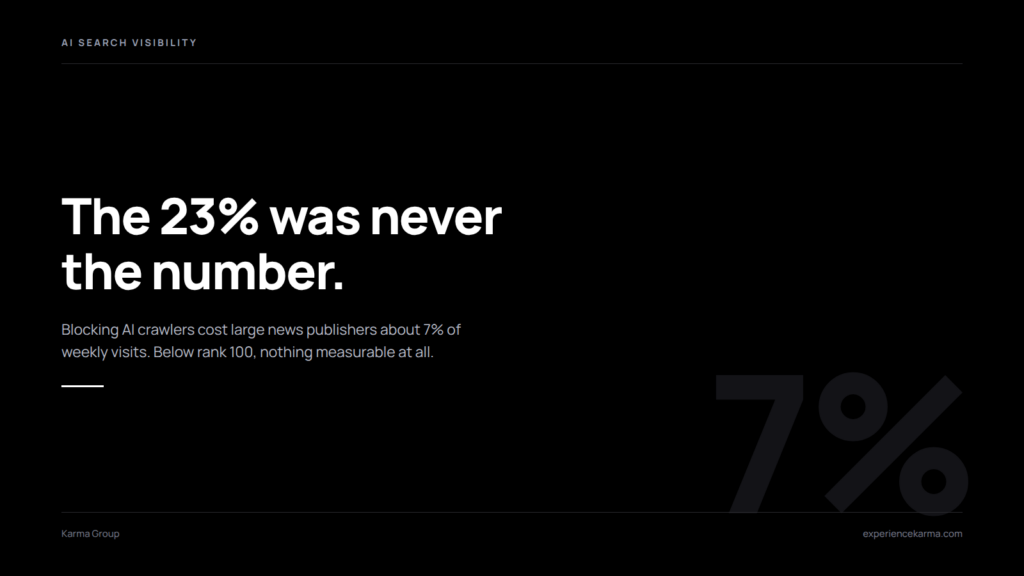
Minus 0.074. That is the headline coefficient in the most-quoted study on blocking AI crawlers, and it works out to roughly a 7% drop in weekly visits. Yet the number still in circulation is 23%. So the figure most people quote at you comes from a draft the authors have since revised, and the revision cut the effect by two thirds. More useful still, it showed the loss concentrates almost entirely among the largest news publishers.
Below rank 100 the measured effect is not a smaller penalty. It sits at zero, and between ranks 101 and 500 the point estimate turns positive. So if you run a brand site rather than a national newspaper, nobody has measured your case. Here is what the evidence actually supports.
The 23% you keep seeing came from a draft
Hangcheng Zhao of Rutgers Business School and Ron Berman of Wharton wrote Strategic Response of News Publishers to Generative AI, first dated 31 December 2025. That original version reported a decline of about 23% in monthly visits for large publishers who blocked AI bots. Trade coverage ran with it, and the number stuck.
Then the authors revised the paper in April 2026. The new version uses a staggered difference-in-differences design following Callaway and Sant’Anna (2021), measured over the 12 weeks before a blocking event and the 6 weeks after. Its headline estimate lands at an ATT of -0.074 on log weekly visits, or about 7%. Both numbers describe the same study. Only one of them still stands.
This matters beyond pedantry. A 23% traffic hit reads as an emergency. A 7% hit reads as a trade-off worth pricing. So the gap between the two versions changes the decision itself, not merely the headline.
Blocking AI crawlers cost large publishers about 7%
The revised paper runs the same test across three independent traffic panels, and they do not agree as neatly as the headline suggests. SimilarWeb returns an ATT of -0.074, significant at the 1% level. Semrush returns -0.069, significant only at the 10% level. Comscore returns -0.065, which clears no significance threshold at all.
That last panel deserves your attention. Comscore measures actual household browsing rather than server-side estimates. So the panel closest to real human behavior is also the one that cannot rule out zero. The direction holds across all three sources. The precision does not.
In short, anyone selling you certainty about blocking AI crawlers is reading one column of that table and quietly ignoring the other two.
The penalty lands on the top 50 and thins out fast
Here is the part nobody has written up, and it does most of the work. The paper breaks its result down by publisher size.
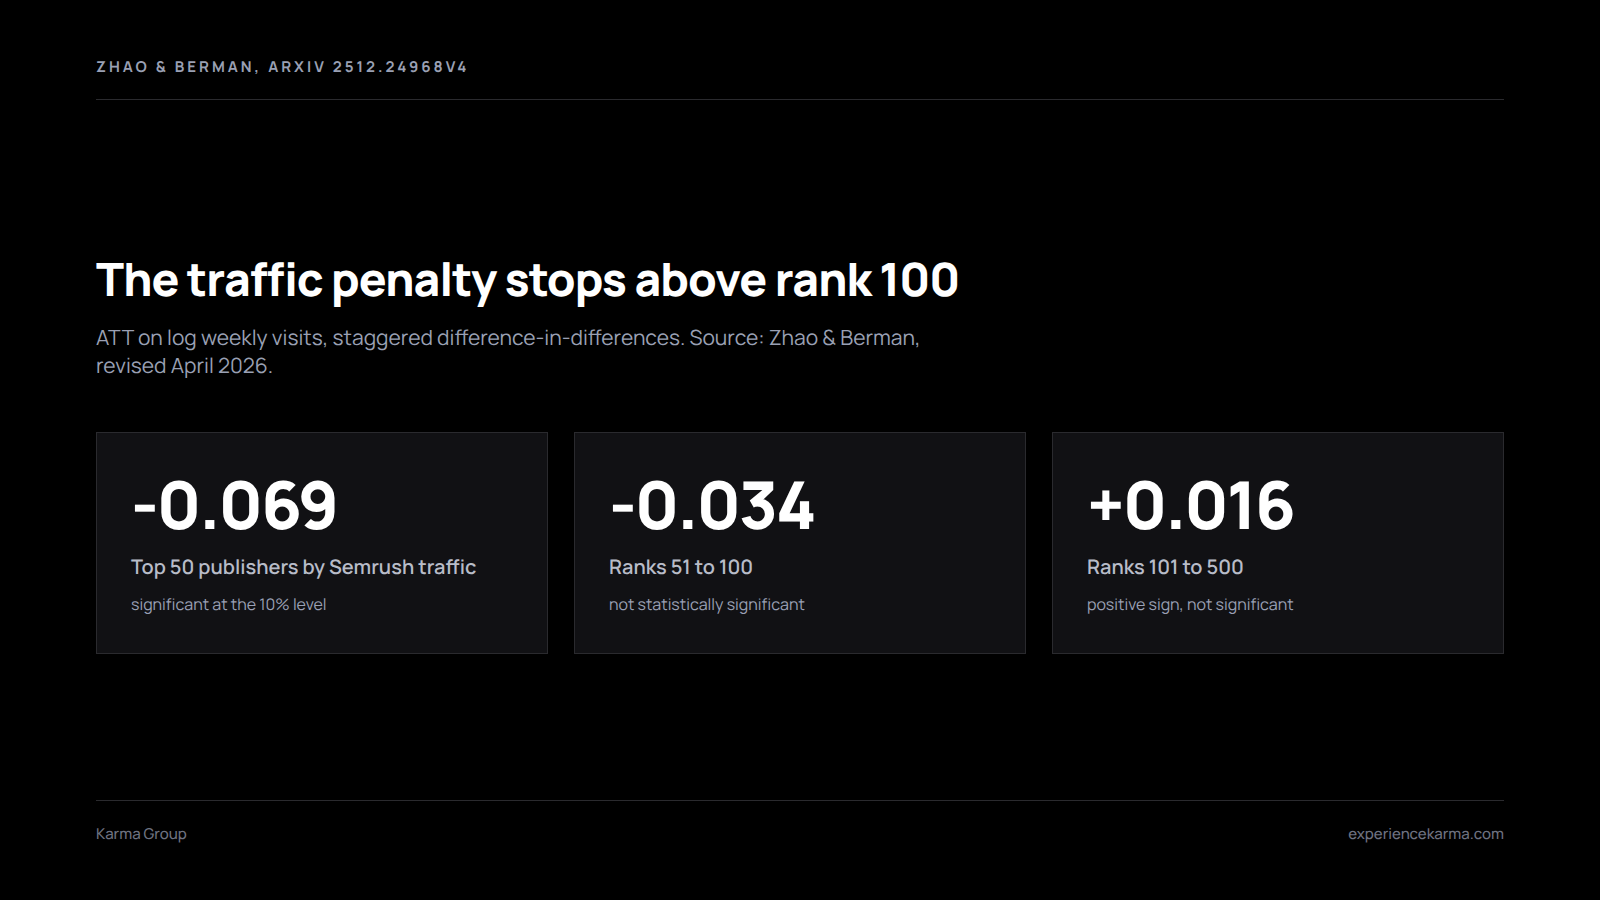
Ranked by Semrush traffic, the top 50 publishers show an ATT of -0.0691. Ranks 51 to 100 show -0.0343. Ranks 101 to 500 show +0.0164, a positive sign. Every one of those confidence intervals crosses zero, so read them as direction rather than measurement. Still, the direction is hard to miss: the penalty concentrates at the top and fades well before the middle.
The Comscore panel splits the same way by traffic volume. Sites above 10 visits a day show -0.0480. Sites below one visit a day show +0.0425. The authors put it plainly. The negative effect concentrates among higher-traffic publishers.
Blocking AI crawlers does not stop the citations
Now the other half of the picture. BuzzStream and Citation Labs analyzed 4 million citations drawn from 3,600 prompts across 10 industries, covering ChatGPT, Gemini, AI Overviews and AI Mode. Their April 2026 analysis is blunt.
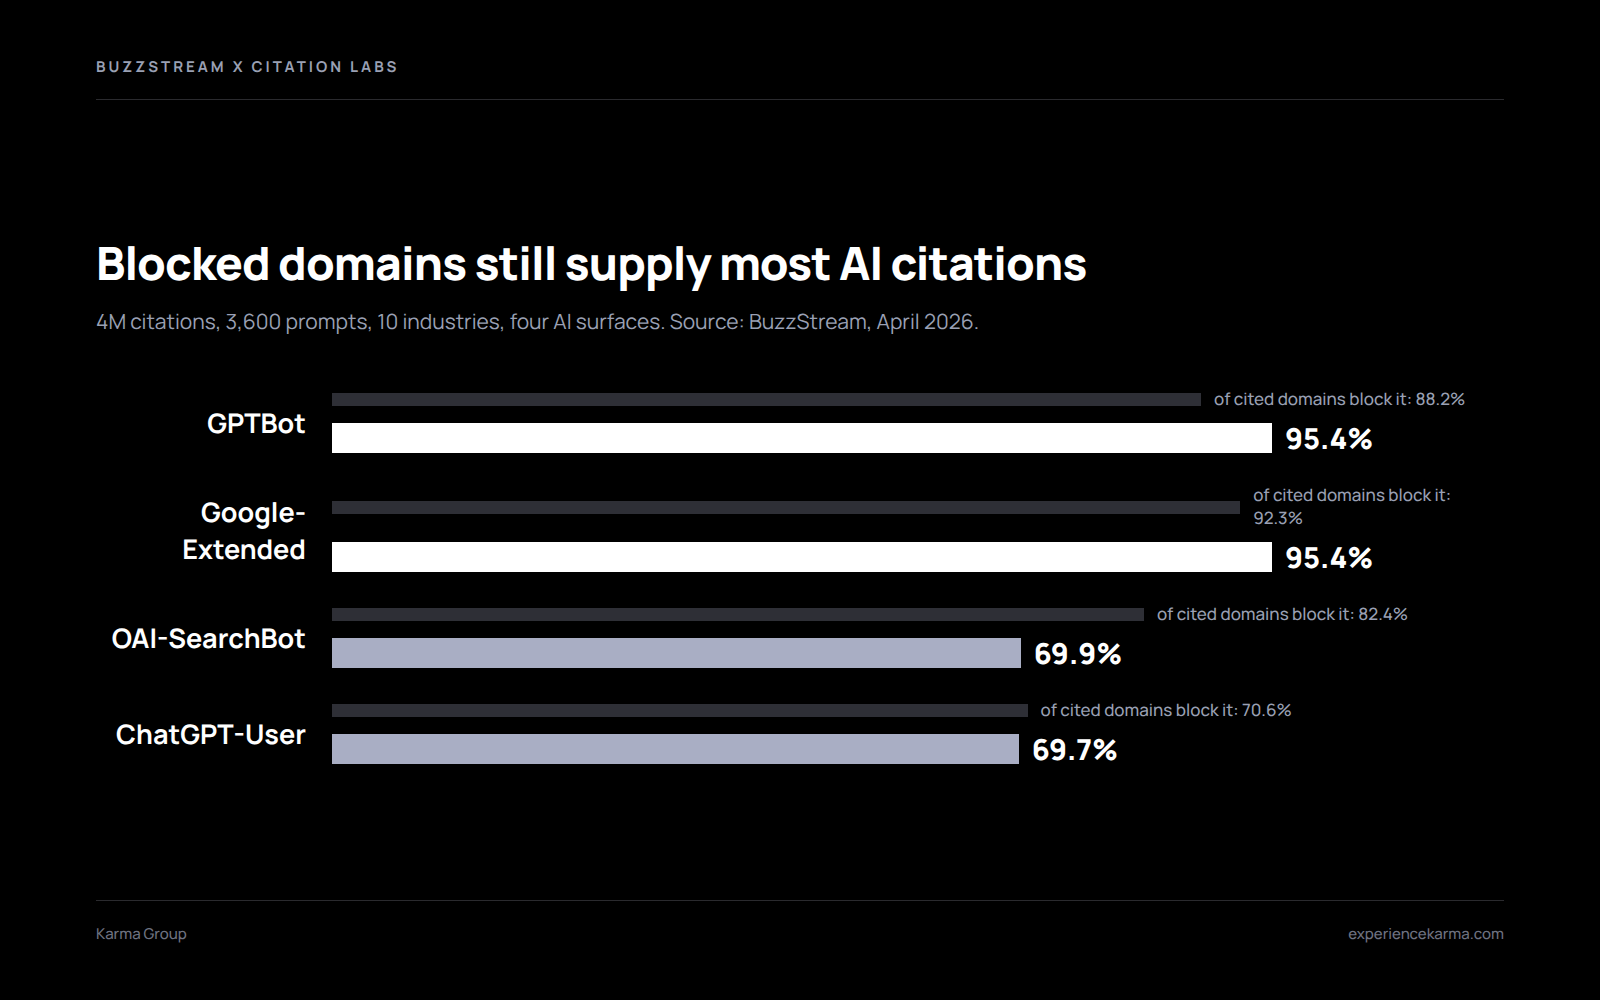
Of the domains AI actually cited, 88.2% block GPTBot, and those blocking domains supply 95.4% of all citations. For Google-Extended the split runs 92.3% and 95.4%. For OAI-SearchBot it runs 82.4% and 69.9%. Read those pairs carefully, because the two figures measure different quantities. The first gives the share of cited domains that block. The second gives the share of citations those blockers still deliver.
So blocking AI crawlers does not remove you from the answer. It removes the visit. That asymmetry should sound familiar if you read our piece on why llms.txt does not work. In both cases, a small text file people believe governs AI behavior turns out to govern much less than advertised.
Your site is not a newspaper
Every figure above comes from news publishers. Zhao and Berman studied 30 newspaper publishers in the main analysis, widening to 500 for robustness checks. BuzzStream studied news domains too. Karma’s clients are brands and exhibit builders, so the transfer is not automatic, and we would rather say that than quietly generalize.
Two things do carry across, though. First, the citation asymmetry describes a mechanism rather than a market quirk: models cite what they already absorbed, so cutting off the crawler cuts tomorrow’s data instead of today’s answer. Second, the size gradient tells you the penalty scales with how much traffic AI surfaces were already sending you.
That cuts both ways, and it is the useful part. If AI referrals amount to a rounding error on your site, then blocking AI crawlers costs you a rounding error. A small brand site has little to lose here, and equally little to gain. So blocking AI crawlers is a low-stakes decision for most brands, which means it deserves rather less agonizing than it currently gets.
The publishers who adapted cut their article count by a third
The same paper carries a second finding that drew even less attention, and it points somewhere more useful than the robots.txt argument. Zhao and Berman also tracked what publishers did to their sites after November 2022, benchmarked against the top 100 retail websites as a control group.
Article volume fell 31.2%. Meanwhile interactive elements rose 68.1%, and advertising and targeting technology rose by roughly 50%. The authors summarize the shift in a single line: publishers do not scale up textual production, but move toward richer pages and embedded components.
Now read that against the advice currently circulating. Most of it tells you to publish more and publish faster, so that AI has more of you to find. Yet the publishers with the most at stake did the opposite. They cut output by nearly a third and spent the effort on pages a model cannot flatten into three sentences.
That is a better lesson for a brand than anything in the blocking debate. Your leverage was never the crawler rule. It is whether the page survives a summary.
What to do instead of blocking AI crawlers
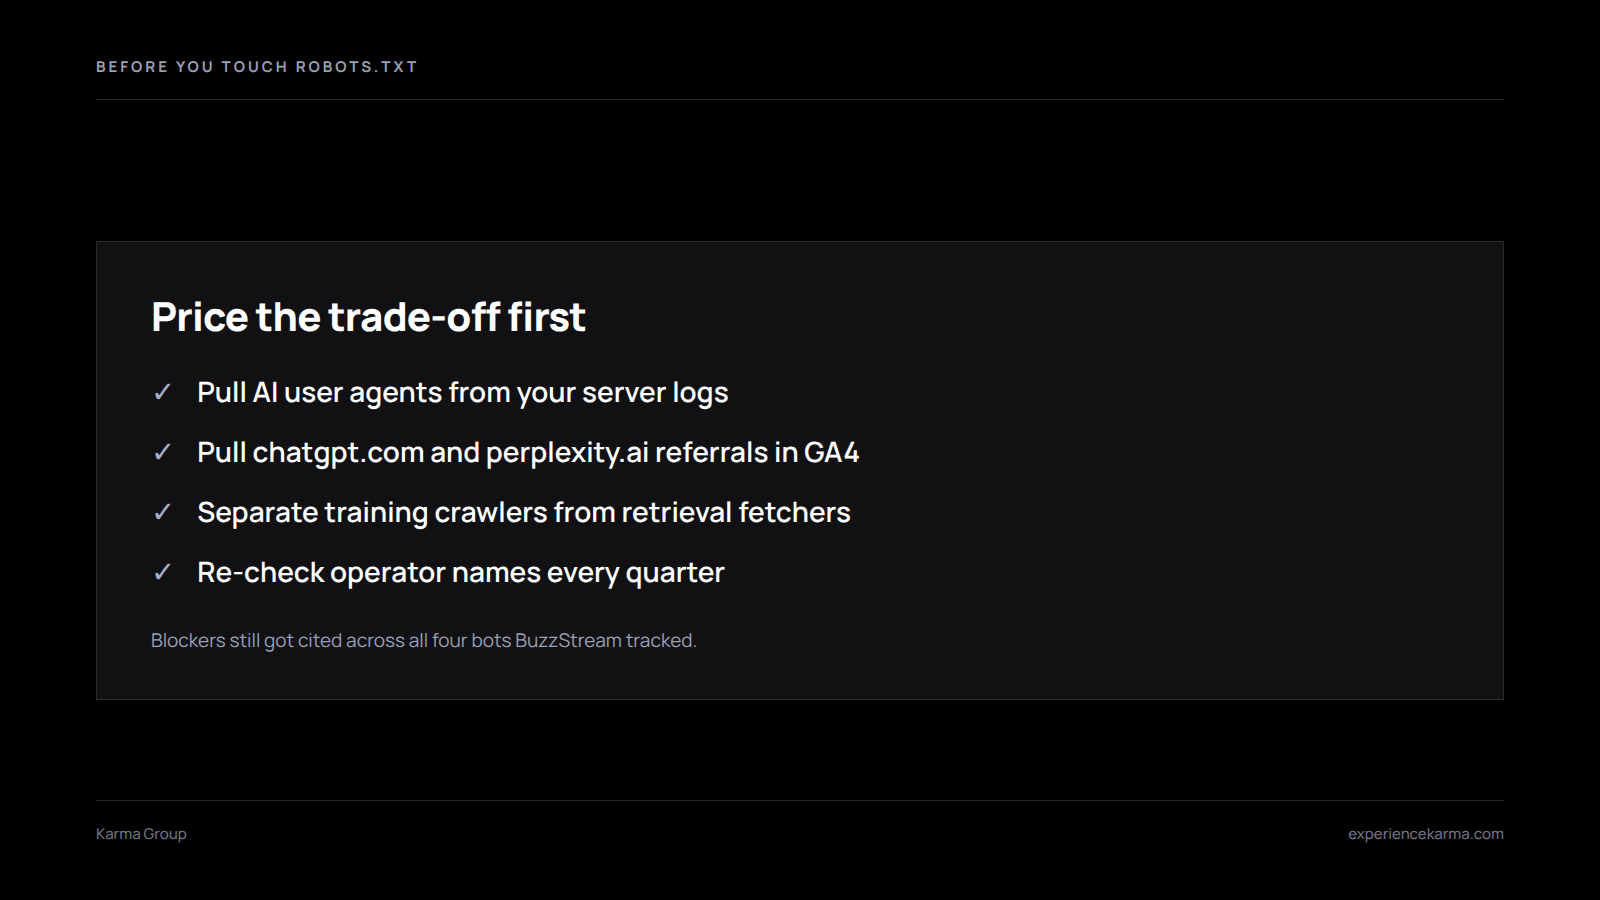
- Measure both sides before you decide. Pull AI user agents from your server logs, then pull referrals from chatgpt.com, perplexity.ai and gemini.google.com in GA4. Until you hold both numbers, you cannot price the trade-off.
- Stop treating every bot as one bot. Training crawlers such as GPTBot and Google-Extended take content without sending anyone back. Retrieval fetchers such as OAI-SearchBot and ChatGPT-User pull pages to build a live answer. Those are separate decisions with separate costs.
- Treat blocking as a rights position, not a visibility lever. Blockers still get cited across all four bots BuzzStream tracked. So block if you object to the training use, but do not expect it to move your visibility either way.
- Skip the blanket robots.txt templates. Most crawler lists circulating this year lump training and retrieval together, so they get this exact distinction wrong.
- Revisit the file every quarter. Operator names keep changing, so a rule set written last year is already out of date.
None of this is dramatic, which is rather the point. The strongest argument against blocking AI crawlers was never the traffic number. It is that the traffic number was doing work it could not support.
Want help reading your own numbers?
Karma Group works with brands on AI search visibility, and we start from your logs and your analytics rather than from someone else’s benchmark. If you want a straight read on what AI surfaces send you today, and what you would actually forfeit by blocking, get in touch.

Written by
Founder and CEO, Karma Group
Brendan Cogbill is the founder and CEO of Karma Group. He has run paid media and search for trade show, experiential and industrial brands since 2019, and now focuses on how brands earn visibility inside AI search. He holds a BBA and an MBA from Grand Canyon University and works from Phoenix, Arizona.
More about Brendan Cogbill